Povej prijatelju o tem izdelku:
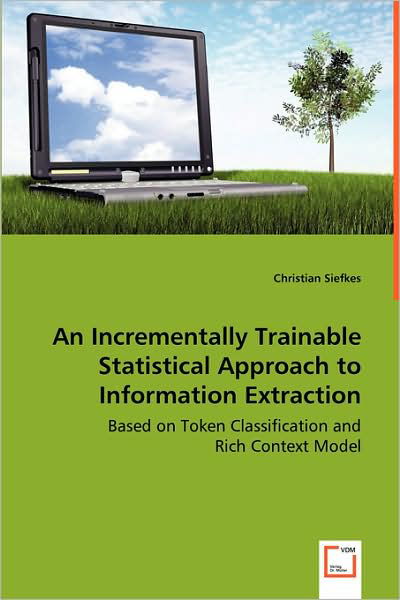
An Incrementally Trainable Statistical Approach to Information Extraction: Based on Token Classification and Rich Context Model Christian Siefkes
Naročeno iz oddaljenega skladišča
Kaj pravijo naše stranke:

An Incrementally Trainable Statistical Approach to Information Extraction: Based on Token Classification and Rich Context Model
Christian Siefkes
Most of the information stored in digital form is hidden in naturallanguage texts. The purpose of Information Extraction (IE) is to finddesired pieces of information in unstructured or weakly structured textsand store them in a form that is suitable for automatic querying andprocessing. This book presents a innovative approach to statistical informationextraction. It introduces a new algorithm which supports functionality notavailable in previous IE systems, such as interactive incremental trainingto reduce the human training effort. The system also utilizes new sourcesof information, employing rich tree-based context representations tocombine document structure (HTML or XML markup) with linguistic andsemantic information. The resulting IE system is designed as a generic framework for statisticalinformation extraction. All core components can be modified or exchangedindependently of each other. This book is of interest for professionals who have to deal with largeamounts of weakly structured information and seek ways to automate thisprocess, as well as for researchers and practitioners active in the fieldsof text mining and text classification.
| Medij | Knjige Paperback Book (Knjiga z mehkimi platnicami in lepljenim hrbtom) |
| Izdano | 4. julija 2008 |
| ISBN13 | 9783639001464 |
| Založniki | VDM Verlag |
| Strani | 220 |
| Dimenzije | 150 × 220 × 10 mm · 299 g |
| Jezik | Angleščina |